
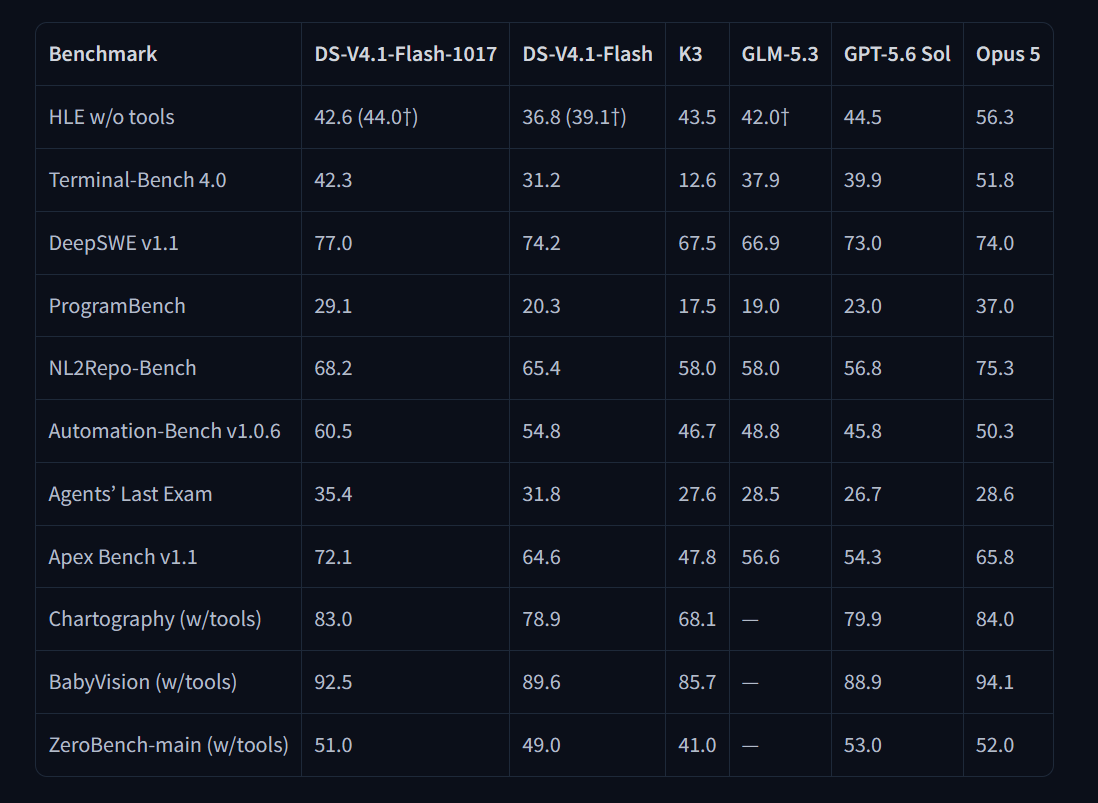
DeepSeek has updated its V4.1 Flash model to DeepSeek-V4.1-Flash-1017. The official October 17 change log reports improvements across reasoning, coding, agentic tasks, and visual benchmarks, along with shorter outputs and faster task completion at a lower overall task cost.
The API name and prices stay the same
For the updated Flash model on DeepSeek's official API, keep using:
deepseek-flash
The official website and app have also moved to the new version. According to the current API model table, the legacy Flash names deepseek-v4-flash and deepseek-v4-flash-vision-exp are served by the 1017 model as well. Third-party providers manage their own deployments and routing.
DeepSeek says the calling method and token prices are unchanged. In that sense, it's an upgrade without a price increase: existing API usage remains billable at the applicable rates.
My quick impression
In my own brief check, output speed didn't feel very different from the previous version — both were around 100 tokens per second. That's an observation from my setup, rather than a controlled speed benchmark.
Still, more capability at the existing rates is welcome. The manufacturer's claim of faster task completion concerns the work as a whole; it doesn't require every individual response to stream faster.
Translated and clarified from the original Chinese article, published on October 17, 2026. The quick test is the original author's; the exact model name, routing, and unchanged pricing were checked against DeepSeek's documentation.
Comments NOTHING