
MiniMax introduced MiniMax-M3.1-Flash-Preview on September 27. For now, access is limited to MiniMax Code and Token Plan rather than the regular public API, according to MiniMax's current documentation.
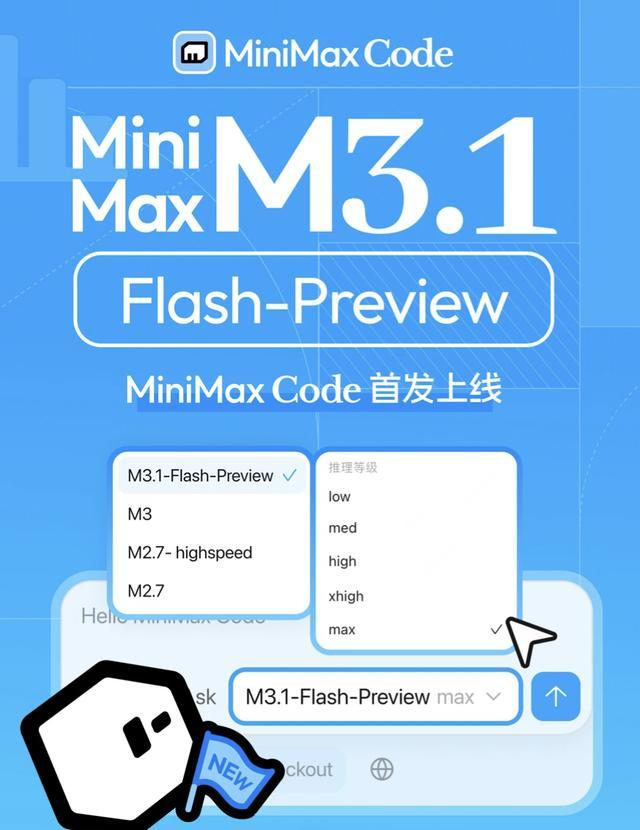
What is available so far
The official model overview lists a 1 million-token context window, multimodal capabilities, and adjustable thinking depth. At the time of the original September 27 post, a parameter count and benchmark results had not been announced.
The launch post also mentions several extra quota resets for Token Plan subscribers around the release. Check your account dashboard for the resets and limits that apply to your subscription.
Speed is promising; coding quality still needs testing
The Flash name suggests an emphasis on speed, which would fit MiniMax's earlier models. I have not tested this preview's coding ability yet, so I am holding off on calling it an upgrade in code quality.
I was already skeptical of M3's coding performance. To compete with DeepSeek, this preview needs to deliver useful speed gains or more reliable code. For developers, a small test on an actual project will tell you more than the model name alone.
If your existing workflow uses a regular MiniMax API key, check availability before changing the model ID: subscription access through MiniMax Code does not automatically mean the preview is exposed through the same public API.
Official model information: MiniMax model overview.
Adapted from the original Chinese article, published on September 27, 2026.
Comments NOTHING