
Z.ai introduced GLM-5.2 with an emphasis on long, complex coding and agent tasks. Its launch comparisons attracted attention for strong frontend results at a relatively low cost.
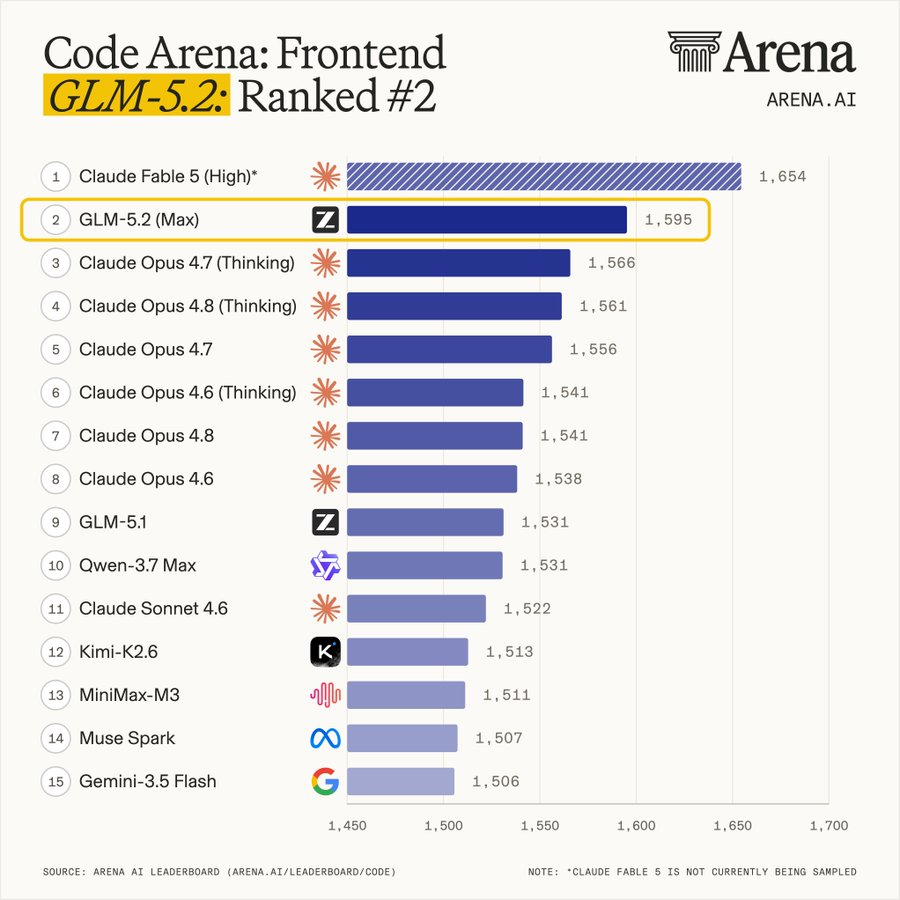
The model has a one-million-token context window. The original announcement compared its coding performance with Claude Opus models and its frontend results with Fable 5. These are evaluation-specific comparisons, not a universal ranking.
The original post noted the lack of multimodal input and concerns about quality over very long contexts. A large advertised window does not guarantee that every detail survives a long session. See Z.ai's announcement and the official model documentation.
Adapted from the original Chinese article, published on June 18, 2026.
Comments NOTHING